ECCV 2026

InteractiveAvatar: Real-Time Streaming Video Generation for Consistent and Intent-Aware Avatars

Quanyue Song★ Yishan He★ Yanfei Zhang Shihao Cheng Zhixiang He Zhizhi Guo† Chi Zhang Xuelong Li Caigui Jiang†

★Equal contribution    †Corresponding author

Paper Code (soon) BibTeX
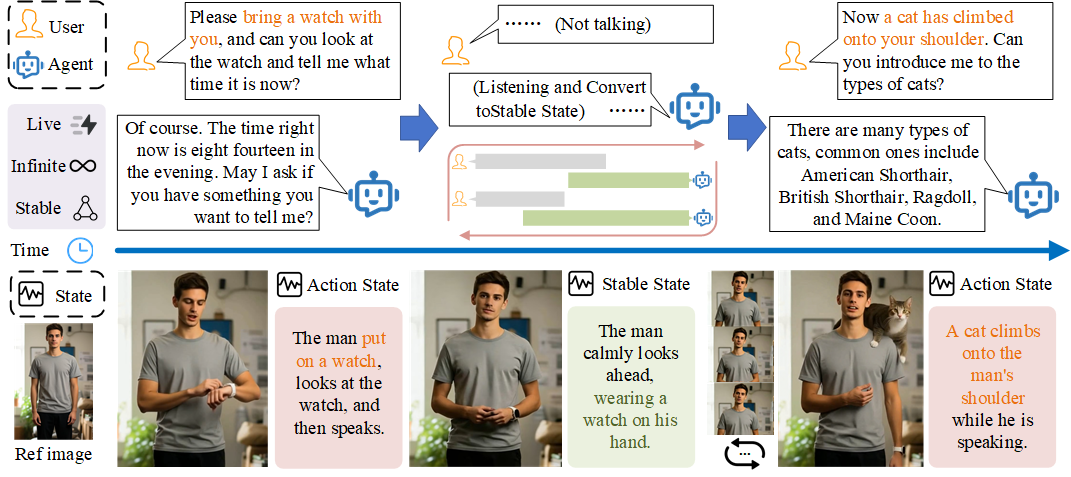
InteractiveAvatar overview

We propose InteractiveAvatar, a real-time streaming audio-driven avatar generation framework that enables intent-aware interaction. InteractiveAvatar interprets user intent to generate contextually relevant actions throughout the dialogue while maintaining long-range visual consistency.

Abstract

Recent diffusion-based models have enabled realistic audio-driven avatar generation in real-time streaming. However, existing approaches struggle to maintain visual temporal consistency and fail to explicitly perceive user intent in complex interactive streaming scenarios. To address these challenges, we propose InteractiveAvatar, a real-time infinite-streaming video generation framework that supports visually consistent avatar video generation and intent-aware interactions. With autoregressive distillation, InteractiveAvatar achieves real-time str-eaming generation of human avatars over arbitrarily long durations. For visual consistency, we introduce a Long-Short Visual Memory (LSVM) mechanism that flexibly compresses historical visual information into compact tokens, preserving both short-range coherence and long-term consistency. To generate avatars with speeches and actions aligned with user intent, we propose a Reasoning-Reaction Module (RRM), which incorporates a State-Cycling strategy and a Cache-Switching mechanism. Extensive experimental results over diverse scenarios demonstrate that our method achieves state-of-the-art visual consistency in long-duration generation, while enabling complex user-avatar interaction in real time.
Method

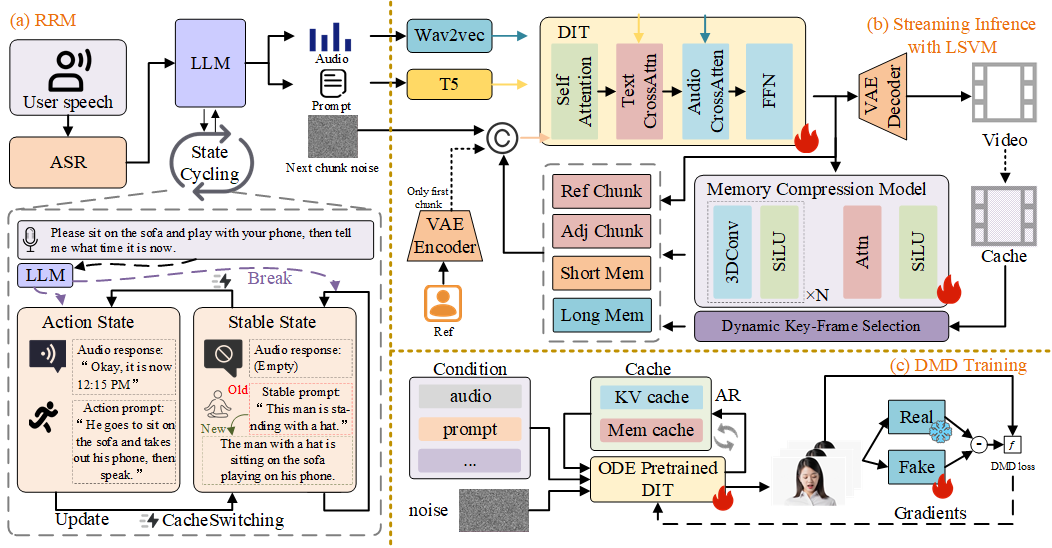
InteractiveAvatar architecture

Overview of InteractiveAvatar, which consists of (a) The Reasoning-Reaction Module (RRM) performs intent-aware interaction with user; (b) Streaming Inference with Long-Short Visual Memory (LSVM) mechanism to enhance the visual consistency; and (c) DMD training for real-time streaming generation.

Real-Time Streaming Framework

A novel real-time streaming audio-driven avatar generation framework that supports long-duration video synthesis with strong visual consistency and intent-aware user-avatar interaction. With autoregressive distillation, InteractiveAvatar achieves real-time streaming generation of human avatars over arbitrarily long durations.

Long-Short Visual Memory (LSVM)

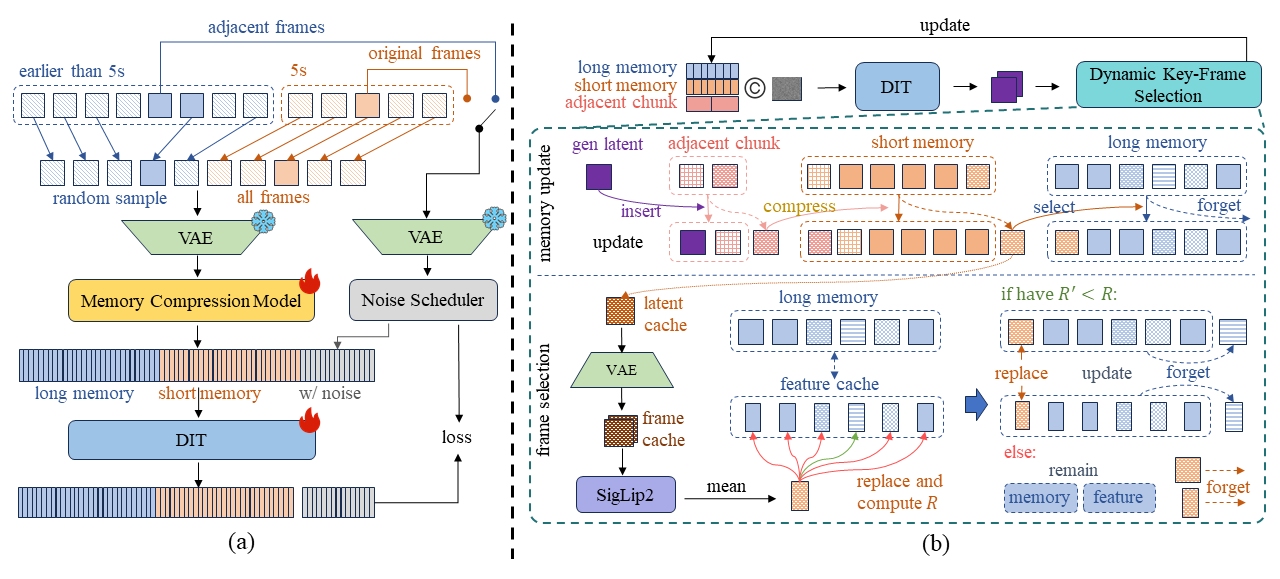
Flexibly preserves historical visual representations by jointly modeling short-term and long-term visual information. A Dynamic Key-Frame Selection strategy adaptively transfers critical content from short-term to long-term memory, significantly improving visual coherence in long-duration generation.

Reasoning-Reaction Module (RRM)

Leverages a large language model for intent understanding, equipped with a State-Cycling strategy for smooth listening-execution transitions and a Cache-Switching mechanism to accelerate action execution and scene transitions with reduced latency.

Long-Short Visual Memory (LSVM)

LSVM Mechanism.(a) During training, long-term memory frames are randomly sampled, while short-term memory retains all recent frames. (b) During inference, Dynamic Key-Frame Selection adaptively updates memory to retain critical visual information.

Results

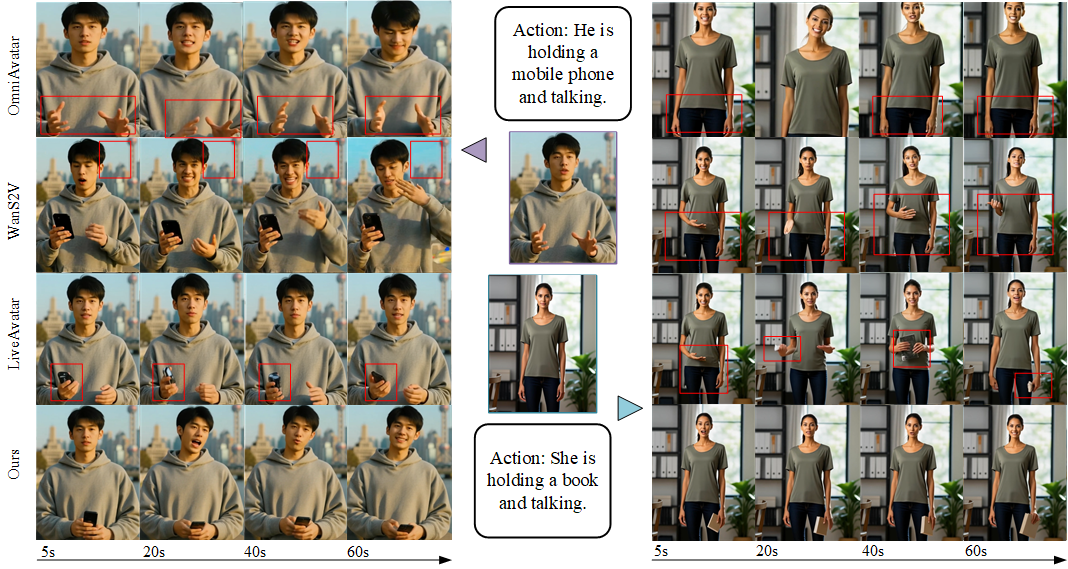
Qualitative comparison

Qualitative comparisons with state-of-the-art methods. Our method exhibits better visual consistency and following of action instructions.

Model Video Quality Consistency SpeedFPS ↑
IQA ↑ ASE ↑ FID ↓ FVD ↓ SynC ↑ SynD ↓ OBJ ↑ ID ↑ TV ↑
StableAvatar3.913.8279.7654.13.5710.2779.54.4125.340.69
OmniAvatar3.773.8794.1831.94.947.8782.84.3824.570.17
HYAvatar3.813.9376.5632.64.788.1178.94.4625.610.09
Hallo33.573.29112.51127.64.219.7475.14.3124.920.28
EchoMimicV33.963.8985.2773.93.8910.0980.34.4525.560.81
WanS2V3.763.6888.4793.54.548.9582.64.4925.140.26
LiveAvatar3.943.9183.9672.74.918.1776.94.5325.7821.94
Ours3.873.8980.2701.44.867.9185.24.5125.9326.68

Quantitative comparison with state-of-the-art methods. Best in bold and second best underlined. Experiments are conducted using the H100 GPU.

Demo Video

Video demo showcasing InteractiveAvatar generating real-time streaming avatar videos with visual consistency and intent-aware interactions.

BibTeX

@misc{song2026interactiveavatarrealtimestreamingvideo,
      title={InteractiveAvatar: Real-Time Streaming Video Generation for Consistent and Intent-Aware Avatars}, 
      author={Quanyue Song and Yishan He and Yanfei Zhang and Shihao Cheng and Zhixiang He and Zhizhi Guo and Chi Zhang and Xuelong Li and Caigui Jiang},
      year={2026},
      eprint={2606.22905},
      archivePrefix={arXiv},
      primaryClass={cs.CV},
      url={https://arxiv.org/abs/2606.22905}, 
}